Uncensored AI Video · Community merge of MiniMax H3
Uncensored MiniMax H3 FL2VA Ref2VA Hybrid: Sharp Video That Remembers Your Characters
MiniMax ships its H3 video model as two separate checkpoints. FL2VA paints the cleaner picture and sound but only listens to a first and last frame; Ref2VA follows a stack of reference photos, clips and voices but looks softer. The community MiniMax H3 FL2VA Ref2VA hybrid stitches both into one file, so a short drama, a fashion reel or an anime character can stay recognizable from shot to shot without losing the polish. Here is what it does, which file to grab and how to prompt it.
- Character consistency
- Native audio
- Open weights
Uncensored Alternative Video Generator
Image to videoUpload a character photo as the first frame, describe the motion, camera and sound, and turn it into a short video.
FL2VA vs Ref2VA: one video model, two personalities
H3 is MiniMax's 33-billion-parameter audio-video model: one network writes the picture and the soundtrack together, so footsteps, waves and dialogue arrive already in sync. Instead of one do-everything file, MiniMax published two checkpoints. FL2VA takes a text prompt plus zero, one or two images, which covers plain text-to-video, first-frame animation, last-frame endings and first-and-last-frame transitions. Ref2VA takes a prompt plus a reference pack of up to nine images, three video clips and three audio clips, twelve files at most.
Both produce 4 to 15 second clips at 24 frames per second with 32 kHz stereo sound and a 768-pixel short side by default. The catch, according to the community authors who tested them side by side, is that FL2VA gives noticeably better picture and audio quality, while Ref2VA is the one that actually remembers who your character is. That trade-off is exactly what the hybrid tries to remove.
| FL2VA | Ref2VA | |
|---|---|---|
| Inputs | Text + up to 2 frames (first, last or both) | Text + up to 9 images, 3 videos, 3 audio clips |
| Best at | Clean picture and sound, first-to-last-frame moves | Keeping faces, outfits, places and voices consistent |
| Weak spot | Cannot follow a character sheet | Softer image quality, per community tests |
| Typical job | Animate a still, bridge two keyframes | Series episodes, outfit showcases, recurring sets |
Why the community fused them into one hybrid model
The insight came from comparing the two files weight by weight. The uploader smhfacct found they are almost identical, with cosine similarity of at least 0.9997, and that the real differences sit in one small layer inside each transformer block, the adaln_proj modulation weights. Swap those layers from Ref2VA into FL2VA and the model borrows the reference skill while keeping most of FL2VA's look and sound.
That is all the MiniMax H3 FL2VA Ref2VA hybrid is: FL2VA as the base, with Ref2VA's modulation layers copied into a chosen range of blocks. No retraining, no blending of averages, just a targeted transplant. It is a community experiment, not a MiniMax release, and both authors describe their judgments as subjective. Still, for anyone who wanted Ref2VA's memory without its blur, it is the most direct fix available today.
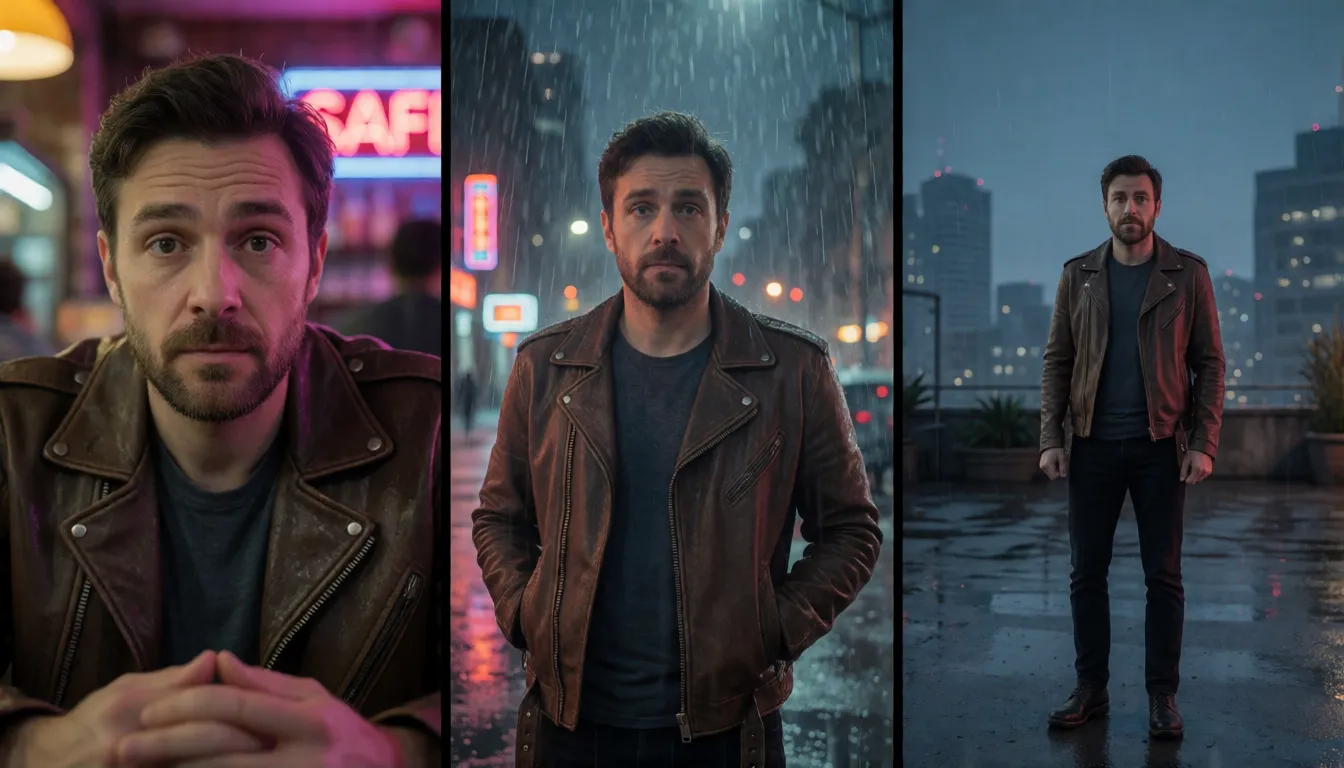
Scenes it handles well: series, fashion reels and recurring sets
Character consistency is the reason people go looking for the MiniMax H3 FL2VA Ref2VA merge. Short-drama makers feed in one headshot and one costume photo, then shoot a cafe confrontation, a rainy street walk and a rooftop goodbye that all star the same face. Because the base is FL2VA, those episodes keep the sharper picture and native sound that make vertical dramas feel finished.
- Episodic stories and AI dramas: one reference portrait carries a lead character through every scene, angle and lighting change.
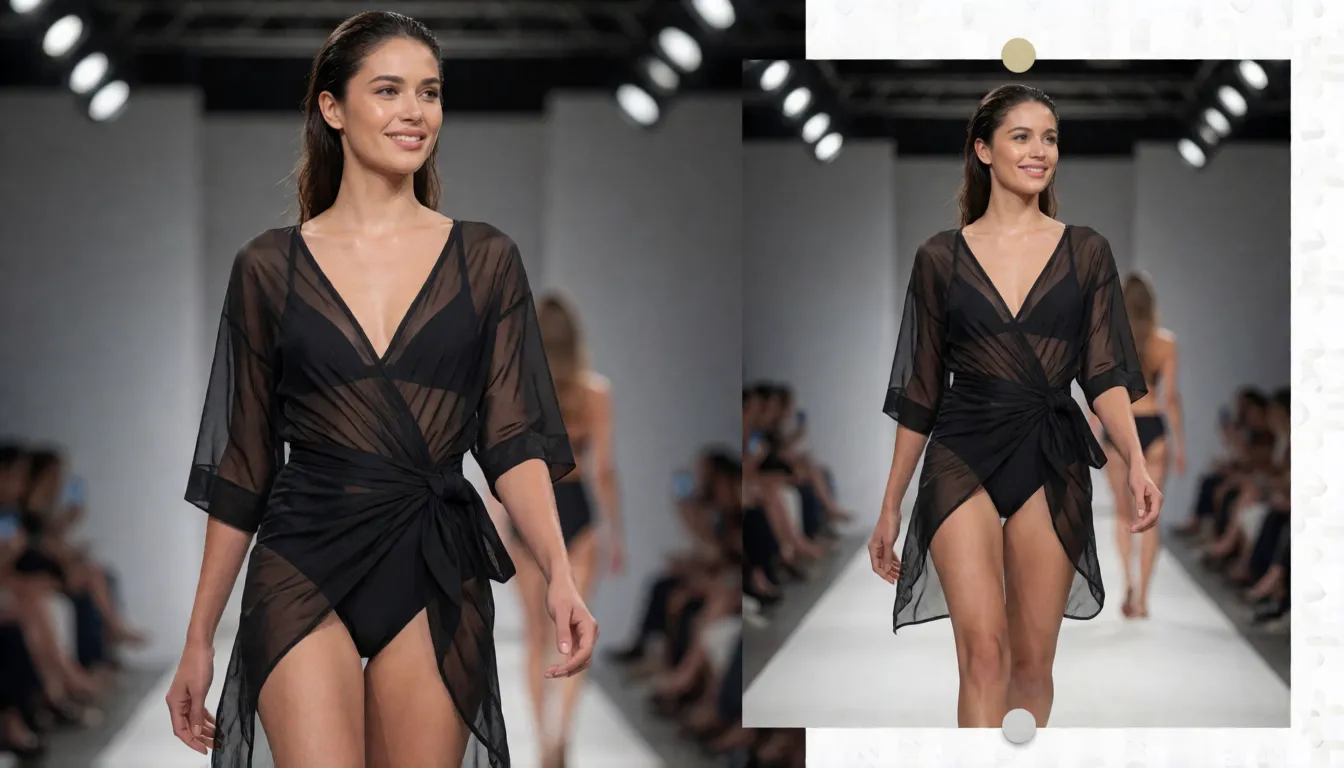
- Outfit and styling showcases: give the outfit as one reference and the model as another, then describe a runway turn or a slow spin. A light-reference file lets the clothes guide the result without freezing the camera.
- Recurring locations: reuse one photo of an apartment, bar or beach and generate new 4 to 15 second shots from different positions.
- Voice and music continuity: Ref2VA accepts 2 to 15 second audio clips, so a character's voice or a theme's mood can repeat across clips. The hybrid keeps this input, though nobody has benchmarked how well.
- Adult (18+) styling: fictional adult characters in swimwear, lingerie or bikini looks for beach, pool and boudoir reels, all running on your own machine.
b15 to b49: picking the right hybrid file
Each file name tells you which blocks received Ref2VA's layers. A wider range means stronger reference following and an image that drifts closer to Ref2VA's softer look; a narrower range keeps more FL2VA polish. smhfacct publishes four int8 files built on a pruned int8 base, while diobrando0 publishes two unpruned bf16 files of about 66.28 GB each that change only the last few blocks.
| File | Precision | Reference strength | Who it suits |
|---|---|---|---|
| b15-49 | int8 | Strongest | Many references, accepts some softness |
| b20-49 | int8 | Strong | Reference-first projects |
| b25-49 | int8 | Balanced | The author's recommended starting point |
| b30-49 | int8 | Moderate | Picture quality first |
| b40-49 | bf16, ~66.28 GB | Light (about 7.9% of weights from Ref2VA) | Subtle guidance at full precision |
| b45-49 | bf16, ~66.28 GB | Lightest | diobrando0's suggested first try |
b25-49 vs b30-49 is the most common debate. Start with b25-49; if faces and costumes already match and you want crisper frames, step down to b30-49. The rule works both ways: if references are ignored, move to a wider range, and if the picture turns mushy or the audio thins out, move to a narrower one.
On hardware, neither author gives a number. They say memory needs match the matching FL2VA file, so the int8 MiniMax H3 FL2VA Ref2VA files sit in the same class as int8 FL2VA, and the 66 GB bf16 files are realistically workstation territory rather than a single consumer graphics card.
Mix your own blend with the AdaLN merge script
diobrando0 ships h3_adaln_merge.py next to the bf16 files. It copies Ref2VA's adaln_proj weights into an FL2VA file byte for byte across the block range you set with --lo and --hi, with no interpolation. It patches the file in place on the CPU in a few minutes, can keep a --backup, undo with --restore, and checks the result with BLAKE2b hashes.
This is handy if b40-49 feels too light and b25-49 too heavy: try b35-49, judge a few clips, and restore if you do not like it. Keep the original Comfy-Org FL2VA and Ref2VA bf16 files around, since the script needs both as sources.
Prompt templates that make references stick
Reference prompts work best in a fixed order: say which reference is which, then the action, then the camera, then the sound. The more references you stack, the more a wider-range file such as b20-49 or b25-49 pays off. These templates are written for the MiniMax H3 FL2VA Ref2VA hybrid and keep every character an adult.
Outfit swap on the beach
The woman from reference image 1, wearing the red bikini from reference image 2, walks along a beach at golden hour. Medium shot, the camera slowly pushes in, she looks back and smiles. Waves and a soft acoustic guitar.
Same character, new scene
The same man from reference image 1 sits in a quiet cafe, close-up side profile. He says quietly: "You're late." Natural window light, 35mm film look, low cafe chatter.
Runway turn
The adult model from reference image 1 walks a white runway in the black swimsuit and sheer wrap from reference image 2, stops, turns slowly. Full-body tracking shot, flashing cameras, deep electronic beat.
Recurring set
In the loft from reference image 1, the couple from reference images 2 and 3 slow dance by the window at night. Wide shot drifting to a two-shot, city lights, soft jazz.
- Name references by number in the order you attached them.
- Describe one main action per clip; 4 to 15 seconds goes fast.
- Write the sound you want, including spoken lines in quotes.
- If a reference keeps being ignored, change the file before rewriting the prompt.
Community verdict and honest limits
Among MiniMax H3 FL2VA Ref2VA uploads, smhfacct's int8 set is the one people talk about: about 384 likes, 14 discussion threads and four Hugging Face Spaces built on it at the time of research. diobrando0's bf16 pair is newer and quieter, with 7 likes, dated September 1, 2026. Both authors stress that their comparisons are by eye, without formal benchmarks, so treat the version table as a starting map rather than a law.
The limits are clear. The hybrid will not beat FL2VA on prompts with no references, the block boundaries were chosen by experiment, memory needs do not shrink, and MiniMax's 2K refinement stage is not open-sourced, so local output stays at the base resolution.
Uncensored H3 hybrid: what is and isn't different
Nothing in the merge removes or adds safety training; only modulation layers move between two official checkpoints. What changes the experience is where it runs. MiniMax's hosted API filters sexual, illegal and infringing content, while open weights on your own machine add no such filter layer, which is why adult creators prefer local H3. Without a big GPU, the image-to-video tool here gives you similar filter-free motion from a single photo for adult (18+) scenes.
Animate a character photo into an 18+ video clip in your browser.
Open image to videoGenerate it online: a no-setup alternative on Spicy AI
Not everyone has a 66 GB workstation or the patience to juggle checkpoints. Spicy AI offers an online alternative generator for the same kind of clip: upload a character photo, describe the motion, camera and sound, and get a short video back in your browser, with no downloads, no drivers and no content filters for adult (18+) scenes.
It suits quick tests before a long local render, phone-only creators and anyone who simply wants the result. Start from one clear photo of your adult character, keep one main action per clip, and reuse the same photo for every episode to keep the face and outfit recognizable.
Try the online image-to-video generator →FAQ
What is the difference between FL2VA and Ref2VA?
FL2VA turns text plus up to two first or last frames into video with sound. Ref2VA uses text plus a reference pack of up to nine images, three clips and three audio files. Community testers say FL2VA has the better picture and audio.
Is the MiniMax H3 FL2VA Ref2VA hybrid made by MiniMax?
No. It is a community merge published on Hugging Face by smhfacct (int8) and diobrando0 (bf16). Both call it experimental and judged by eye.
Which hybrid file should I download first?
Start with b25-49 for the int8 set or b45-49 for the bf16 set. Move to a wider range if references are ignored, or a narrower one if quality drops.
How much VRAM does the hybrid need?
The authors only say a MiniMax H3 FL2VA Ref2VA file matches the corresponding FL2VA file. The bf16 files are about 66.28 GB, the int8 files are smaller, and no official memory figure exists.
Can I speed it up?
Yes. The ref2v turbo 4-step LoRA works with it for fast drafts, and you can always run full steps without the LoRA for final renders.
Sources
More uncensored AI video models
- Uncensored MiniMax H3
- Uncensored MiniMax H3 Max
- Uncensored Kling
- Uncensored Kling 2.6
- Uncensored Kling O1
- Uncensored Sora
- Uncensored Veo
- Uncensored Hailuo AI
- Uncensored Wan
- Uncensored Wan 3.0
- Uncensored Seedance
- Uncensored Seedance 2.5
- Uncensored Seedance 2.0
- Uncensored Seedance 2.0 Mini
- Uncensored HunyuanVideo
- Uncensored LTX Video
- Uncensored Runway
- Uncensored Pika
- Uncensored Luma Dream Machine
- Uncensored Vidu
- Uncensored PixVerse
- Uncensored EdenLive
- Uncensored Grok Imagine
- Uncensored AI Avatars
- Uncensored HappyHorse 1.0
- Uncensored Kling 4.0
- Uncensored Kling 3.0
- Uncensored MiniMax H3 RefMods
- Uncensored Kandinsky 6.0
MiniMax and H3 are trademarks of their respective owner. The hybrid files are community work. All content must depict adults (18+).